Advanced Seedance 2.5 Prompts: 5 Expert Patterns, Tested (2026)
Five advanced Seedance 2.5 prompts, tested across 8 clips and verified frame by frame: camera control, multi-shot timing, audio clauses and exact costs.
Most "advanced Seedance 2.5 prompt" guides I have read are lists of adjectives. Cinematic. Hyper-detailed. 8K. Those words do very little, and the guides never show you the clip that came out, which is the only evidence that matters.
So I ran the experiment properly. Eight generations on Seedance 2.5, most of them matched pairs where one clause in the prompt changed and everything else was held: same seed, same duration, same resolution, same aspect ratio.
Five patterns came out of it, each with its before and after sitting side by side so you can judge it yourself. One of them buys back a third of your screen time. One costs nothing and saves you four minutes waiting on a render that was never going to be delivered.
1. Write the prompt as the dolly path, in order
The single most useful thing I know about this model: the order you list objects in becomes the order the camera passes them. You are not writing a description of a scene. You are writing the route the camera takes through it.
Parameters duration: 8 | resolution: 720p | aspect_ratio: 16:9 | seed: 42 | generate_audio: true
One 8-second continuous take, $1.905489. Scene detection at a 0.2 threshold found zero cuts.
Here are eight frames pulled at even intervals, left to right.

Lens cases, then tripods, then flight cases, then the technician. The list in the prompt is the list on screen, in sequence.
Frames one to three are the wall of lens cases. Four and five are the tripods. Six and seven are the flight cases. Eight is the technician with the camera body. That is the prompt read out loud, in order, as one unbroken move.
Two things make this work. The first is writing the beats as a sequence with "then" and "ending on" rather than as a pile of nouns. The second is No cuts, which the model honours reliably: zero scene changes here, and zero in every single-take prompt I gave it.
It is worth saying what does not happen, because it gets written up wrongly. An underspecified prompt does not get chopped into shots. Give Seedance 2.5 six vague words and it will invent one competent continuous move and make every other decision for you. The failure mode of a thin prompt is lost control, not lost continuity.
The rule: list what the camera passes in the order it passes it, and say where the move ends. If you want one take, write No cuts.
2. Describe framing relative to the subject, never in absolute terms
This is the one that cost me the most clips before I understood it. Seedance 2.5 executes camera instructions close to literally, and "chest height" is a height instruction. It is not a shot size.
Two fires, identical in every respect except one clause. Same carpenter, same workshop, same seed, same six seconds.
Parameters duration: 6 | resolution: 720p | aspect_ratio: 16:9 | seed: 42 | generate_audio: true
Parameters duration: 6 | resolution: 720p | aspect_ratio: 16:9 | seed: 42 | generate_audio: true
Absolute: "locked at chest height"
Relative: "chest to just above the head"
Both clips: 6s, 720p, 16:9, seed 42. The only difference is how the framing was described. Each billed $1.431585.
The left clip does exactly what it was told. The camera sits at chest height and the carpenter's head is out of frame for the entire six seconds. You get a torso, an apron, two arms and a plane. It is a faithful execution of the prompt and it is unusable.
Absolute framing: head cropped in all six frames

Subject-relative framing: head held in frame throughout

Six frames pulled at even intervals from each clip. The absolute clause never recovers; there is no frame in the six seconds where the face appears.
The right clip reads the same scene and gives you a working medium shot with the face in it the whole way through. Nothing else in the prompt changed. No extra adjectives, no "cinematic", no quality words.
The rule: anchor every framing instruction to the subject's body, not to a height above the floor. "Holds her from the waist up", "frames him head to knees", "stays tight on the hands" all work. "At eye level", "at chest height", "low angle at 30cm" will be obeyed as geometry, and geometry does not know where the face is.
3. Give every shot an explicit time budget
Seedance 2.5 will cut between shots if you prefix them with Shot 1:, Shot 2: and so on. That part is documented and it works. What is not documented is how it divides the clip, and the answer is: not evenly, and not in your favour.
Parameters duration: 15 | resolution: 720p | aspect_ratio: 16:9 | seed: 42 | generate_audio: true
Parameters duration: 15 | resolution: 720p | aspect_ratio: 16:9 | seed: 42 | generate_audio: true
No time budget
Five seconds stated per shot
Both clips: 15s, 720p, 16:9, seed 42, $3.564153 each. Cut timestamps measured with ffmpeg scene detection.
Scene detection on the unbudgeted clip puts the cuts at 6.08s and 11.54s. That is a 6.08 second opener, a 5.46 second middle, and a 3.53 second payoff. The wide of the finished pot, which is the entire point of the sequence, gets the scraps.
Adding four words to each beat moves the cuts to 4.88s and 10.04s: 4.88, 5.16, 5.03. Within a fifth of a second of the 5/5/5 I asked for.
No time budget: 6.08s / 5.46s / 3.53s

Budgeted: 4.88s / 5.16s / 5.03s

Six evenly spaced frames from each. On the top strip the finished pot appears only in the final frame; on the bottom it holds for two.
The pattern is that the model front-loads. It spends its time on the setup and compresses whatever you put last, so the shot you care most about is the one most likely to be cut short. Four words per shot fixes it, and it costs nothing: both clips billed identically at $3.564153, because you are paying for 15 seconds of output either way.
The rule: if a prompt has more than one shot in it, put the seconds in every shot. "Shot 3, five seconds:" is the whole technique.
4. End every audio clause with "no music"
Seedance 2.5 co-generates audio in the same pass, and generate_audio defaults to true. That is genuinely useful and, as the cost section below shows, it is free. There is one trap in it.
The content-safety pass runs on the finished audio track, not on your prompt. So a prompt that asks for music renders all the way through, and then gets refused at the door. I fired one deliberately:
Parameters duration: 5 | resolution: 720p | aspect_ratio: 16:9 | seed: 42 | generate_audio: true
HTTP 400  (after 145.3 seconds)
{
  "blocked_side": "output",
  "finish_reason": "OutputAudioSensitiveContentDetected.PolicyViolation",
  "rai_category": "copyright",
  "error": "The generated audio was blocked by content-safety filters ...
            if you do not need audio, set generate_audio to false and retry.
            You have not been charged for this request."
}
Two and a half minutes of render time, no video, no charge. Nothing in the prompt names a track, an artist or a studio. It asked for music, the model wrote some, and the filter would not release it.
The fix is in the wording. Describe diegetic sound, the noise the scene itself makes, and close the clause with "no music". The other seven prompts in this run all ended that way and every one of them passed. You can see the pattern in the prompt boxes above: "quiet workshop room tone, the rasp of the plane and wood shavings falling to the floor, no music."
Build the retry in rather than re-rolling the same request: if finish_reason contains OutputAudioSensitiveContentDetected, refire with generate_audio: false. That is what the error text itself now tells you to do, and it is what gets you a usable clip on the second attempt instead of a second refusal.
One more thing the meter showed. Seedance mixes quiet. Integrated loudness across these clips ran from -26.7 to -41.9 LUFS, against a -14 LUFS streaming target. The 8-second warehouse take came back at -41.9 with a -20.3 dBFS true peak, which is close to inaudible on a phone. Whatever you generate, normalise it before you publish it.
The rule: name the room tone and the props that make noise, end with "no music", and lay a licensed track over the top in post if you need one.
5. A 480p draft tests your wording, not your shot
The standard advice, including the advice on Segmind's own model page, is to draft at 480p and re-fire at 720p once you like it. 480p is 55.5% cheaper, so the logic is obvious. The problem is what "once you like it" implies.
I fired the same prompt twice at seed: 42, same six seconds, same 16:9. The only difference was resolution.
Parameters duration: 6 | aspect_ratio: 16:9 | seed: 42 | generate_audio: true | resolution: 480p vs 720p
480p draft ($0.636754)
720p final ($1.431585)
Identical prompt, identical seed, identical duration. Resolution is the only variable.
These are not the same shot at two sizes. They are two different takes. The 480p version plays out on dark polished stone with the barista out of frame entirely, lit hard from a backlit window. The 720p version puts the cup on pale marble with the barista's torso in shot and a softer, brighter room.
480p: dark stone counter, no barista in frame
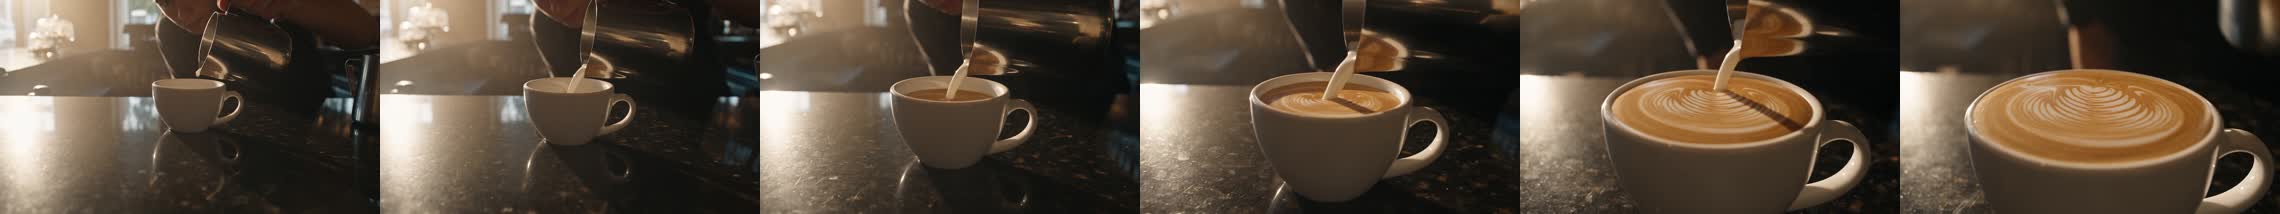
720p: pale marble counter, barista in shot

What survived the resolution change is everything the prompt actually named: the pour, the rosetta, the window light from the left, the slow push in, no cuts.
Look at what did transfer, though, because that is the useful part. Both clips deliver the pour, the finished rosetta, the light from the left, the slow push in and zero cuts. Every element the prompt named survived. Everything it left to the model was re-rolled.
The rule: use a 480p fire to check whether your wording produces the right action, the right light and the right props. Do not use it to check composition, and never send one to a client as a preview of the 720p deliverable. If you need reproducibility, hold the seed, the duration and the resolution together; any one of them moving is enough to get a new take.
What each of these actually costs
Seedance 2.5 bills on output tokens, and the token count is not an estimate. It is a formula, and every fire in this run matched it to the cent:
720p:  tokens = 21600 * seconds + 900
480p:  tokens =  9608 * seconds + 397
1080p: tokens = 2.25 * (21600 * seconds + 900)

cost = tokens * rate, rate = $10.97/M at 480p and 720p, $11.99/M at 1080p
The +900 is not request overhead. 900/21600 is exactly 1/24, and the model outputs 24fps. You are billed for the duration you asked for plus one single frame. That one constant is the whole explanation for why the per-second price looks slightly sublinear as clips get longer.
Per-second tokens track output pixels exactly. 9608/21600 is 0.4448, and 854x480 over 1280x720 is 0.4448 to four places, which is why 480p is a flat 55.5% cheaper at every duration. 1080p works out at 2.459x the 720p price.
| Duration | 480p | 720p | 1080p |
|---|---|---|---|
| 4s | $0.4260 | $0.9577 | $2.3551 |
| 5s | $0.5314 | $1.1946 | $2.9379 |
| 6s | $0.6368 | $1.4316 | $3.5206 |
| 8s | $0.8476 | $1.9055 | $4.6860 |
| 10s | $1.0584 | $2.3794 | $5.8514 |
| 15s | $1.5854 | $3.5642 | $8.7650 |
| 20s | $2.1124 | $4.7489 | $11.6786 |
| 30s | $3.1663 | $7.1184 | $17.5057 |
Cost per clip, computed from the token formula. Every 720p and 480p figure in this run matched the x-cost header exactly.
The practical upshot: you can price a shot list before you fire a single request. A 12-shot sequence at 8 seconds each in 720p is $22.87, and you know that before you start rather than after.
Two more things worth knowing. Failed generations bill $0.00, so iterating on parameters is free. And generate_audio is free as well: audio on and audio off land within a thousandth of a cent of each other, because you are billed on the video tokens either way. There is no reason to turn audio off to save money.
Four things that will bite you
Wall clock is unpredictable, cost is not. The eight fires in this run took between 2 and 5 minutes each, and across a larger sample I have seen the same 720p configuration come back anywhere from 77 seconds to over 10 minutes. Duration is a weak predictor. Budget your pipeline by cost, set your HTTP timeout above 600 seconds, and never promise a completion time in a user-facing flow.
1080p returns HEVC 10-bit and browsers will not play it. The 1080p path comes back as hvc1, Main 10, yuv420p10le. Drop that straight into a <video> tag and Chrome and Firefox show a silent black box even though the file is perfectly good. Transcode for the web with libx264 -crf 18 -pix_fmt yuv420p and keep the original for grading.
Check the orientation on vertical output. I have had a 9:16 request come back as a correct 720x1280 portrait container with landscape content rotated 90 degrees inside it, no rotation metadata, no error, billed in full. It is intermittent rather than systemic, but nothing in the response tells you it happened. If you publish vertical at any volume, pull one frame and look at it.
The spec contradicts itself on skip_moderation. The parameter list documents Default: true while both code examples on the same page send false. Do not rely on either. Send the value you want explicitly on every request.
FAQ
What makes a good Seedance 2.5 prompt?
Specificity about the camera, not about quality. Words like "cinematic" and "8K" change very little. A clause describing where the camera starts, what it passes and where it ends changes the output substantially, because the model executes that clause almost literally.
How do I control the camera in Seedance 2.5 prompts?
Write the shot as a path in the order you want it travelled, and describe framing relative to the subject rather than in absolute terms. "Holds him from the chest to just above the head" is safe. "Locked at chest height" is a height instruction, and the model will obey it even if that means cropping the head off.
Does Seedance 2.5 support multi-shot prompts?
Yes. Prefix each beat with Shot 1:, Shot 2: and so on, and the model will cut between them. It does not divide the time evenly on its own, so state the seconds you want for each shot or the final beat gets squeezed.
Why does my Seedance 2.5 video get rejected for copyright?
Because the moderation pass runs on the finished video and audio, not just on the prompt. Asking for music is the most common trigger. Describe diegetic room tone instead and end the audio clause with "no music". The refusal bills $0.00 but costs you the full render time.
Should I draft at 480p before rendering at 720p?
Only to test your wording. A 480p draft is 55.5% cheaper and will confirm the beat, the lighting and the wardrobe, but the same prompt and seed produce a different take at a different resolution. Never show a 480p draft to a client as a preview of the 720p deliverable.
How much does a Seedance 2.5 video cost?
At 720p it is (21600 * seconds + 900) tokens at $10.97 per million, so a 5-second clip is $1.194633 and a 30-second clip is $7.118433. The full table is above, and it is exact rather than indicative.
Where I would start
If you take one thing from this, make it the time budget on multi-shot prompts. It is four extra words per shot, it costs nothing, and in my test it was the difference between a payoff shot that lands and one that flashes past in three and a half seconds.
After that, rewrite your camera clauses as paths rather than as adjectives, and check your framing language for absolute terms that the model will take at face value. Those three habits fixed more in my outputs than any amount of quality vocabulary ever did.
All of this runs on one API call. You can try Seedance 2.5 on Segmind, and if you want to price a sequence before you commit to it, the formula above will tell you the bill to the cent.